> ## Documentation Index
> Fetch the complete documentation index at: https://docs.primeintellect.ai/llms.txt
> Use this file to discover all available pages before exploring further.
# Algorithms
This page covers the math and the configurable algorithmic components: the algorithm abstraction and its algorithms, how off-policy training works, the loss components and advantage functions, curricula, and how multi-turn rollouts get merged into training samples.
## Table of Contents
* [The Algorithm Abstraction](#the-algorithm-abstraction)
* [Model References](#model-references)
* [The Algorithms](#the-algorithms)
* [Customizing Components](#customizing-components)
* [Per-Env Algorithms](#per-env-algorithms)
* [The Algorithm Classes](#the-algorithm-classes)
* [Async / Off-Policy Training](#async--off-policy-training)
* [Loss](#loss)
* [Loss Components](#loss-components)
* [IPO Loss](#ipo-loss)
* [Custom Loss](#custom-loss)
* [Advantage](#advantage)
* [Default Advantage](#default-advantage)
* [Hierarchical GRPO](#hierarchical-grpo)
* [Self-Play Advantage (RAE)](#self-play-advantage-rae)
* [Authoring an Algorithm](#authoring-an-algorithm)
* [Reference Scoring](#reference-scoring)
* [Curricula](#curricula)
* [Multi-Turn Trajectories](#multi-turn-trajectories)
* [Extension Property](#extension-property)
* [Best-Effort Interleaving](#best-effort-interleaving)
* [Renderers](#renderers)
* [Discontinuous Trajectories](#discontinuous-trajectories)
## The Algorithm Abstraction
A training algorithm in `prime-rl` is configured under `[orchestrator.algo]`, where **`type` names the algorithm** (`grpo`, `opd`, `sft`, …) and the class defaults are its vetted setting. It has two parts:
1. **Sampling** (`algo.sampling`) — how train rollouts are produced: which model generates them. `source` is a [model reference](#model-references): `"policy"` (the live policy, the default) or an inline frozen hosted model. Group sizing stays on the env config (`group_size`).
2. **The per-token training signal** — credit assignment and loss routing, fused; the algorithm's own parameters sit directly on `algo`. One mapping from a finalized rollout to per-token *(loss component, weight)* pairs — the credit a token gets and the loss that consumes it are two coordinates of the same output. Group-relative algorithms compute credit on the orchestrator and ship per-token advantage streams; reference-KL algorithms query a reference model at batch-ship time (bounded concurrency) and ship its prefill logprobs for the trainer to evaluate against the live policy. The `type` determines which loss component consumes the action tokens (`rl` / `ce` / `ref_kl`) and what happens to env-provided observation tokens in multi-turn rollouts (masked out by default; `echo` trains on them with weighted CE).
The trainer is algorithm-blind: the loss is a sum of three components (rl, ce, ref\_kl), each normalized by its own global token count; per-token streams ship on the wire (the `rl_weights` / `ce_weights` / `ref_kl_weights` component weights plus the `advantages` stream on each training sample) and the trainer just executes them. Adding an algorithm never touches the dispatcher, batch packing, or trainer hot path.
### Model References
`prime-rl` hosts exactly one model: the trainable policy (`[orchestrator.model]`). Every other model an algorithm uses is an external OpenAI-compatible endpoint, declared *inline on the component that uses it*. A model reference is either the string `"policy"` (the live policy) or a frozen hosted model (`name` + `base_url`):
```toml theme={null}
[orchestrator.algo]
type = "opd"
[orchestrator.algo.teacher] # opd's teacher: the frozen model it scores against
name = "Qwen/Qwen3-32B"
base_url = "http://localhost:8001/v1"
```
Model *roles* are algorithm-local vocabulary — each algorithm names its reference on the field where the model is actually used, and there is no shared `teacher` slot. `opd` declares a `teacher` field (the frozen model whose reverse KL the policy distills toward); `sft`'s teacher *is* its `sampling.source` (the frozen model it imitates); `opsd` self-distills against the live policy and names no model at all. No role exists outside the algorithm that declares it: the dispatcher, sink, and trainer branch on liveness alone, never on what an algorithm calls a model.
So for `opd` set `[orchestrator.algo.teacher]`; for `sft` set `[orchestrator.algo.sampling.source]`; `opsd` needs neither. `opd`'s teacher must be a frozen endpoint — it is typed `FrozenModelConfig`, so `"policy"` isn't representable (the KL would be identically zero); `opsd`'s teacher *is* the live policy by definition (self-distillation conditioned on a demonstration), so it exposes no reference to configure.
Liveness is a property of the reference, not of any role: rollouts sampled from `"policy"` get version-salted prefix caches, carry sampling logprobs for importance ratios, and age off-policy as weights update; rollouts and scores from frozen models get a stable prefix cache and never go stale. Frozen models are externally hosted (`base_url` is required) — `prime-rl` never launches or updates them, and each env's algorithm builds its own client pool to the endpoints it declares.
### The Algorithms
The `algo.type` names the algorithm, and each type's class defaults are its vetted setting — picking a type with no other keys IS the algorithm:
```toml theme={null}
[orchestrator.algo]
type = "grpo" # the default
```
| `type` | Sampling | Loss | What it is |
| ------------------- | --------------- | ----------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `grpo` | policy | `rl` on actions | Standard group-relative RL. |
| `max_rl` | policy | `rl` on actions | MaxRL ([arXiv:2602.02710](https://arxiv.org/abs/2602.02710)): GRPO's centered reward normalized by the group **mean** instead of the standard deviation — the gradient is unbiased for the order-`group_size` truncation of the maximum-likelihood objective, upweighting hard examples like `1/p`. |
| `rae` | policy | `rl` on actions | RAE (SPIRAL, [arXiv:2506.24119](https://arxiv.org/abs/2506.24119)): reward minus a per-agent EMA baseline of that agent's own rewards — the estimator for multi-agent self-play envs, where the group mean would mix the agents' opposite reward scales. See [Self-Play Advantage](#self-play-advantage-rae). |
| `hierarchical_grpo` | policy | `rl` on actions | GRPO for proposer-solver envs. Solvers are compared only with attempts on the same proposed problem; proposers are compared with the other proposals in the group. See [Hierarchical GRPO](#hierarchical-grpo). |
| `opd` | policy | `ref_kl` on actions | On-policy distillation ([Thinking Machines](https://thinkingmachines.ai/blog/on-policy-distillation/)): the policy samples, per-token reverse KL against a reference model as the gradient signal. Needs a `teacher`. |
| `sft` | *(the teacher)* | `ce` on actions | Hard distillation: a frozen model generates rollouts, the policy trains with CE on its tokens. Needs a frozen `sampling.source` (the teacher it samples from). |
| `opsd` | policy | `ref_kl` on actions | SDFT ([arXiv:2601.19897](https://arxiv.org/abs/2601.19897)): the model is its own reference, conditioned on an expert demonstration. The teacher *is* the live policy (the paper's setting, no extra deployment) — no model to configure. |
| `echo` | policy | `rl` on actions + weighted `ce` on observations | ECHO: standard GRPO plus a cross-entropy loss on env-provided tokens already present in the rollout, selected by message role (needs the renderer's role attribution). Defaults to tool-response bodies at `alpha = 0.1` (ECHO's λ); set `roles` to train other roles, each at its own weight. |
### Customizing Components
Every key beyond `type` is visibly your own assembly — there is no preset layer to diverge from. The vetted setting is the class defaults; what you set is what runs:
```toml theme={null}
# echo on tool AND user feedback tokens, each at its own weight.
# Setting any role replaces the whole table.
[orchestrator.algo]
type = "echo"
[orchestrator.algo.roles.tool]
alpha = 0.25
[orchestrator.algo.roles.user]
alpha = 0.05
```
A new algorithm is a named class in code, not a config that points at an import path — see [Authoring an Algorithm](#authoring-an-algorithm).
Echo also takes an optional user-supplied token filter that narrows the role selection per rollout — e.g. dropping warning lines from tool output, or tokens the sampler found unlikely:
```toml theme={null}
[orchestrator.algo.filter]
import_path = "my_module.drop_warnings"
[orchestrator.algo.filter.kwargs]
patterns = ["WARNING"]
```
```python theme={null}
# my_module.py — sees the raw rollout (message text, sampling logprobs);
# returns one keep-mask per trainable branch, spanning that branch's
# token_ids. False = never echo-trained.
def drop_warnings(rollout, *, patterns: list[str]) -> list[list[bool]]: ...
```
Component compatibility is validated at config time: frozen-model sampling can only feed the `ce` loss component — the `rl` and `ref_kl` components need the live policy's own sampling logprobs for importance ratios — `opd` pointed at `"policy"` is rejected as degenerate (zero KL), `sft` without a frozen source is rejected (CE on the policy's own tokens is not a distillation target). A group-relative algorithm with `group_size = 1` produces all-zero advantages; the resulting empty batch is caught at runtime (the orchestrator warns and aborts after repeated zero-trainable batches), not at config time.
### Per-Env Algorithms
Both components resolve per environment. Each env inherits `[orchestrator.algo]` unless it sets its own, so a single run can mix algorithms across envs — e.g. GRPO on math, ECHO on a terminal env:
```toml theme={null}
[orchestrator.algo]
type = "grpo"
[[orchestrator.train.source]]
name = "math" # inherits the top-level grpo
env.taskset.id = "math"
env.agent.harness.id = "null"
env.agent.runtime.type = "subprocess"
[[orchestrator.train.source]]
name = "terminal"
env.taskset.id = "terminal"
env.agent.harness.id = "bash"
env.agent.runtime.type = "subprocess"
# this env runs its own algorithm
algo.type = "echo"
```
### The Algorithm Classes
At runtime, each env's resolved config builds two objects: a `GenerationSource` (`prime_rl.orchestrator.generation_source`) that resolves the `sampling.source` model into the inference pool used for train episodes, and one of the named algorithm classes in `prime_rl.orchestrator.algo` (one module per algorithm: `algo/grpo.py`, `algo/opd.py`, …) from the algorithm config. Algorithm dispatch is keyed on `algo.type` — it names the algorithm, and each config class's defaults are its vetted parameterization:
| `algo.type` | Class | hook(s) — stage |
| ------------------- | --------------------------- | ------------------------------------------------------------------------------------------------ |
| `grpo` | `GRPOAlgorithm` | `score_group`: group-norm credit (optional length penalty) |
| `echo` | `EchoAlgorithm` | `score_episode`: weighted ce on observation tokens; `score_group`: group-norm credit (inherited) |
| `max_rl` | `MaxRLAlgorithm` | `score_group`: mean-normalized group credit |
| `rae` | `RAEAlgorithm` | `score_group`: per-agent EMA-baseline credit |
| `hierarchical_grpo` | `HierarchicalGRPOAlgorithm` | `score_group`: GRPO baseline per episode for solvers, per group for the proposer |
| `opd` | `OPDAlgorithm` | `score_episode`: own-context prefill under the teacher |
| `opsd` | `OPSDAlgorithm` | `score_episode`: demo-conditioned prefill under the live policy |
| `sft` | `SFTDistillAlgorithm` | no credit assignment; CE on sampled tokens |
Algorithms operate on native verifier artifacts and annotate their message graphs directly:
* `async score_episode(episode)` — rollout-local scoring as one episode arrives.
* `async score_group(episodes)` — group-relative scoring after the cohort completes.
The pipeline drives these through `finalize_episode` and `finalize_group`. Advantages, reference logprobs, and named loss weights stay on verifier nodes through admission. Only admitted traces are flattened into `TrainingSample`s.
Class-level declarations state what the algorithm needs: which loss component its action tokens feed (`action_loss_type`). Every class is constructed with its algorithm config plus the one host-owned resource it can't rebuild — the live policy clients (`self.clients`). Everything else an algorithm needs it builds from its own config in `setup()`: `opd` connects its frozen `teacher`; `opsd` builds the renderer for its demonstration hint (tokenizer is always the live policy's — self-distillation has no separate model). The pipeline only ever calls the two `finalize_*` methods — writing your own algorithm is subclassing `Algorithm` and overriding the hooks its signal needs (see [Authoring an Algorithm](#authoring-an-algorithm)). Shared math (efficiency shaping, prefill alignment) lives as plain functions in `prime_rl.orchestrator.algo.advantage`.
## Async / Off-Policy Training
`prime-rl` is asynchronous by default. The trainer and inference always run one step overlapped: while the trainer is producing $\pi_n$ from rollouts at step $n$, inference is already generating the rollouts for step $n+1$ using $\pi_{n-1}$. With matched trainer and inference step times this produces fully-overlapped pipeline parallelism — neither side ever idles.
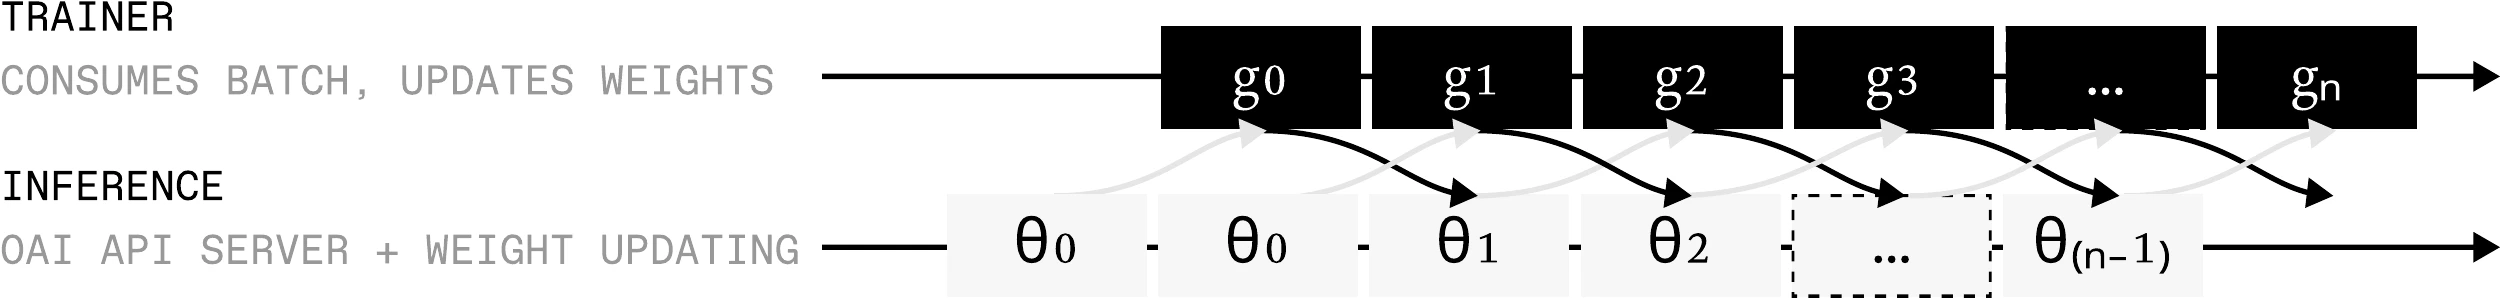 At step $n = 1, 2, 3, \dots$:
* **Trainer** produces policy $\pi_n$ with weights $\theta_n$ from rollouts $(x_n, y_n)$.
* **Inference** produces rollouts $(x_n, y_n)$ from policy $\pi_{\max(0,\,n-1)}$.
Step indices are 1-indexed; policy versions are 0-indexed, with $\pi_0$ the base model. At step 1 inference samples from $\pi_0$.
## Loss
### Loss Components
The training loss is a **sum of three components**, each with its own per-token weight stream and its own normalization:
$$
\mathcal{L} = \frac{\sum \mathcal{L}_{rl}}{N_{rl}} + \frac{\sum \mathcal{L}_{ce}}{N_{ce}} + \frac{\sum \mathcal{L}_{ref\_kl}}{N_{ref\_kl}}
$$
* `rl` — the configured RL loss (`[trainer.loss]`): IPO by default, or a [custom loss](#custom-loss). Fed by the advantage-assigning algorithms (`grpo`, `max_rl`, `rae`, `hierarchical_grpo`, and `echo`'s action tokens).
* `ce` — masked NLL. Used for frozen-model tokens (`sft`) and env-observation tokens (`echo`).
* `ref_kl` — the per-token reverse KL to a reference model ($\log \pi_{\text{ref}} - \log \pi$) as the policy-gradient signal, importance-ratio corrected with a one-sided trust region (`opd`, `opsd`). Requires `ref_logprobs` from a [reference scoring](#reference-scoring); the scoring model must be a vLLM server (it's the only one that exposes `prompt_logprobs`).
The orchestrator stamps each sample's component membership as per-token weight streams (`rl_weights` / `ce_weights` / `ref_kl_weights` on the wire): a weight scales that component's per-token loss, `0.0` leaves the token out of the component entirely (mask *and* denominator), and components may overlap on the same token — their gradients sum. Each $N$ is the global (all-reduced) count of that component's member tokens, so the components don't dilute each other: adding echo observation tokens never changes the rl term's effective per-token learning rate, and an sft env packed next to a GRPO env doesn't soften its gradient. Tokens of different components pack freely into the same micro batch, and a plain GRPO run ships no weight streams at all (absent streams mean rl weight 1.0 on every trainable token — the unchanged hot path). Advantages always ship per token (`advantages` on the wire), assigned as per-token streams from the start — uniform group credit is broadcast over completion tokens at assignment; algorithms with no rl credit (opd, opsd) ship none.
### IPO Loss
The default RL loss is Importance Policy Optimization (IPO). It combines an importance-weighted policy-gradient term with a squared log-ratio KL regularizer. A symmetric trust region removes tokens whose absolute probability change exceeds $\epsilon$:
$$
\mathcal{L}(\theta) = \frac{1}{N}\sum_t
\left[
-\mathbb{1}\!\left(\left|\pi(y_t)-\mu(y_t)\right| \le \epsilon\right)
\tau_A \hat{A}_t \frac{\pi(y_t)}{\mu(y_t)}
+ \tau_{KL}\log^2\!\left(\frac{\pi(y_t)}{\mu(y_t)}\right)
\right].
$$
$\mu$ is the policy that generated the rollout. $\pi$ is the current trainer policy. $\hat{A}_t$ is the token-level advantage. The trust region uses the sampled token probabilities, not their ratio.
The knobs under `[trainer.loss]` are:
| Knob | Default | What it does |
| --------- | ------- | -------------------------------------------------------------------------------------------------------------- |
| `eps` | 0.1 | Maximum absolute probability change before a token is masked. |
| `adv_tau` | 1.0 | Temperature on the advantage term. Set to 0 to drop the policy-gradient term, leaving only the KL regularizer. |
| `kl_tau` | 1e-3 | Temperature on the KL regularizer. Set to 0 to disable. |
Omit `[trainer.loss]` to use these defaults. Set `type = "ipo"` when you specify the section. The `ce` and `ref_kl` components are fixed and unaffected by `[trainer.loss]`.
### Custom Loss
`[trainer.loss] type = "custom"` replaces the `rl` component. The loss is computed **per sequence**: you write a function that takes one sequence's tensors and returns a scalar loss. The trainer iterates and aggregates. `inputs.loss_mask` selects exactly the rl member tokens (for a plain GRPO run, all trainable tokens).
```python theme={null}
# my_module.py
import torch
from prime_rl.trainer.rl.loss import LossInputs, LossOutputs
def ppo_clip_loss(inputs: LossInputs, clip_eps: float = 0.2) -> LossOutputs:
ratio = torch.exp(inputs.trainer_logprobs - inputs.inference_logprobs)
clipped = torch.clamp(ratio, 1 - clip_eps, 1 + clip_eps)
surr1 = ratio * inputs.advantages
surr2 = clipped * inputs.advantages
loss = -torch.min(surr1, surr2)[inputs.loss_mask].sum()
return LossOutputs(
loss=loss,
metrics={
"clip_frac": (ratio != clipped)[inputs.loss_mask].float().mean(),
},
)
```
Wire it up:
```toml theme={null}
[trainer.loss]
type = "custom"
import_path = "my_module.ppo_clip_loss"
[trainer.loss.kwargs]
clip_eps = 0.2
```
The dataclasses:
```python theme={null}
@dataclass
class LossInputs:
trainer_logprobs: Float[Tensor, "seq"] # current policy
inference_logprobs: Float[Tensor, "seq"] # rollout-time policy
ref_logprobs: Float[Tensor, "seq"] | None # set by reference-scoring algorithms
advantages: Float[Tensor, "seq"]
loss_mask: Bool[Tensor, "seq"] # this component's member tokens
loss_weights: Float[Tensor, "seq"] | None # the component's weight stream (None = 1.0)
@dataclass
class LossOutputs:
loss: Float[Tensor, ""]
metrics: dict[str, Tensor]
```
Anything you put in `metrics` is averaged across sequences and logged with the other trainer metrics.
## Advantage
The per-token training signal is set by `algo.type` and the [algorithm](#the-algorithm-abstraction)'s parameters — every signal is a per-token advantage stream, varying in evaluation site (orchestrator vs. trainer). The `algo.type` values:
| Type | Component | Effect |
| ------------------- | ----------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `grpo` | `rl` | Group-norm: reward minus per-group baseline, optional length penalty. |
| `max_rl` | `rl` | Mean-normalized group credit (maximum-likelihood RL). |
| `rae` | `rl` | Reward minus a per-agent EMA baseline (SPIRAL's role-conditioned advantage estimation) — for multi-agent self-play envs. |
| `hierarchical_grpo` | `rl` | GRPO for proposer-solver envs: solvers are compared within one proposed problem, while proposers are compared across proposals. |
| `echo` | `rl` + `ce` | Group-norm on action tokens, plus weighted CE on env-provided tokens selected by message role (each role's `alpha` is its ECHO λ), optionally narrowed by a user filter. |
| `opd` | `ref_kl` | On-policy distillation: per-token reverse KL to a reference model (`teacher`, an inline frozen hosted model), evaluated in the trainer from shipped reference logprobs. No credit — rollouts keep `advantages = None` and ship no advantage stream; `group_size` only fans out sampling. |
| `opsd` | `ref_kl` | SDFT: per-token reverse KL to a demo-conditioned reference. No credit — rollouts keep `advantages = None` and ship no advantage stream. |
| `sft` | `ce` | Cross-entropy on the sampled tokens. Assigns no advantage — trains on every sampled token. |
### Default Advantage
The default advantage is per-group reward minus per-group baseline (DR-GRPO without std normalization). For each prompt's group of `group_size` rollouts, every token in rollout $i$ receives advantage $s_i - \bar{s}$ where $\bar{s}$ is the group mean.
This is intentionally simple — it does the right thing for most envs. Write a named algorithm class when you need group-aware shaping that depends on trajectory metadata (sub-agent rollouts, relative-rank shaping, …) — see [Authoring an Algorithm](#authoring-an-algorithm).
A **length penalty** (`length_penalty` on the `grpo`-family algorithms) can be layered on top to discourage rambling. The `linear` penalty subtracts a single `pass_rate`-scaled penalty from each reward before the GRPO baseline, combining output tokens (`num_output_tokens_weight`), input / context tokens (`num_input_tokens_weight`), and turns (`num_turns_weight`) — each normalized by the group's own max for that quantity, with `num_input_tokens_weight` and `num_turns_weight` defaulting to `0.1`.
```toml theme={null}
[orchestrator.algo]
type = "grpo"
[orchestrator.algo.length_penalty]
type = "linear"
```
### Hierarchical GRPO
GRPO gives each rollout its reward minus the average reward of comparable rollouts. In an ordinary single-agent group, every rollout answers the same task, so one group average is enough.
A proposer-solver env is different. Starting from one source task, it produces several proposed problems, then runs several solver attempts on each problem:
```text theme={null}
one source task
├── proposed problem A
│ ├── proposer trace
│ ├── solver attempt 1
│ └── solver attempt 2
└── proposed problem B
├── proposer trace
├── solver attempt 1
└── solver attempt 2
```
The solver attempts for A should not be compared with the solver attempts for B: the two problems may have very different difficulty. Proposer and solver rewards should not be compared either: they measure different jobs.
`hierarchical_grpo` therefore chooses the average separately for each role:
| Trace | Compared with | Why |
| -------- | -------------------------------------------------- | ----------------------------------------------------------------- |
| Solver | Other solver attempts on the same proposed problem | They attempted the same problem. |
| Proposer | Other proposer traces in the group | They started from the same source task and proposed alternatives. |
For example, if three solvers receive rewards `[1, 1, 0]` on one proposed problem, their average is `2/3` and their advantages are `[1/3, 1/3, -2/3]`. Solver rewards from other proposed problems do not affect those values. The proposers are scored separately according to how useful their problems were for the solvers, then compared with the other proposers in the group.
Configure which roles are compared within a single proposed problem with `episode_agents`. For `proposer-solver`, that role is `solver`:
```toml theme={null}
[orchestrator.algo]
type = "hierarchical_grpo"
episode_agents = ["solver"]
[[orchestrator.train.source]]
name = "proposer-solver"
group_size = 4 # proposed problems per source task
env.n = 4 # solver attempts per proposed problem
env.taskset.id = "proposer-solver"
env.proposer.harness.id = "null"
env.proposer.runtime.type = "subprocess"
env.solver.harness.id = "null"
env.solver.runtime.type = "subprocess"
```
`group_size` controls how many problems are proposed from each source task. `env.n` controls how many solvers attempt each proposed problem. If a comparison contains only one trace—for example, a solver when `env.n = 1`—its advantage is zero.
This algorithm is accepted only for proposer-solver envs. Use the env's `train_proposer` and `train_solver` settings if you want to train only one role.
### Self-Play Advantage (RAE)
Group-relative baselines assume the group is exchangeable attempts by one agent. A multi-agent self-play env breaks that: one episode yields one trace per agent, all trainable, and in a zero-sum game the rewards sum to \~0 whatever the policy does — the group mean carries no information, and centering against it converts any structural asymmetry (a first-mover edge) into permanent credit for one agent.
`rae` implements SPIRAL's role-conditioned advantage estimation ([arXiv:2506.24119](https://arxiv.org/abs/2506.24119)): each agent keeps an exponential-moving-average baseline of its own rewards, and every trace's advantage is its reward minus its agent's baseline — measured against the *pre-update* baseline (the unbiased order), then folded in at `decay` (SPIRAL's α, default 0.95). The algorithm instance is per-env, so baselines are keyed per (env, agent) — the paper's per (game, role). Advantages are not normalized, and `group_size` is free (RAE needs no sibling rollouts; `group_size = 1` is fine). Baselines live in orchestrator memory and re-warm from 0 over \~`1/(1 − decay)` traces per agent after a restart.
```toml theme={null}
[orchestrator.algo]
type = "rae"
decay = 0.95
[[orchestrator.train.source]]
name = "kuhn-poker"
env.taskset.id = "kuhn-poker"
env.player0.harness.id = "null"
env.player0.runtime.type = "subprocess"
env.player1.harness.id = "null"
env.player1.runtime.type = "subprocess"
```
Both of `kuhn-poker`'s agents late-bind to the run's own model — shared-policy self-play against a continuously improving opponent. Pin one agent to a frozen endpoint (`env.player1.model = ...`) for asymmetric play; its traces are marked untrainable by the env and never reach the advantage computation. A single-agent env under `rae` degrades to REINFORCE with an EMA baseline.
### Authoring an Algorithm
There is no config hook that points at user code — a new credit-assignment scheme is a new named algorithm in the repo. Subclass `Algorithm`, assign credit in the scoring hook whose timing fits your signal, and register the class:
```python theme={null}
# src/prime_rl/orchestrator/algo/my_algo.py
import torch
from prime_rl.orchestrator.algo.base import Algorithm
from prime_rl.orchestrator.algo.routing import assign_advantages
class MyAlgorithm(Algorithm):
async def score_group(self, episodes):
traces = [trace for episode in episodes for trace in episode.traces]
rewards = torch.tensor([trace.reward for trace in traces], dtype=torch.float32)
advantages = ... # one value per trace
for trace, advantage in zip(traces, advantages.tolist(), strict=True):
assign_advantages(trace, advantage)
```
Add a typed `MyAlgoConfig` to `prime_rl.configs.algorithm` and its discriminated union, then register `"my_algo": MyAlgorithm` in `ALGORITHM_CLASSES`. Pick `score_episode` for rollout-local work or model calls, and `score_group` for group-relative credit. `assign_advantages` takes a scalar or a list aligned to the trace graph's sampled tokens.
Curriculum admission and metrics can inspect the resulting graph-native streams after group scoring.
### Reference Scoring
`OPDAlgorithm` / `OPSDAlgorithm` do their model I/O in `score_episode`: as each episode arrives they query a reference and attach sampled-token reference logprobs to its graph nodes:
* `opd` — score each sample's own context under the `teacher` (a frozen [model reference](#model-references)) via prefill; fills `ref_logprobs` for the `ref_kl` loss component (on-policy distillation). The `teacher` is typed `FrozenModelConfig`, so `"policy"` isn't representable (the KL would be identically zero).
* `opsd` — SDFT: prepend an expert demonstration as a leading system message (`template`, with a `{demonstration}` placeholder) and score the sample under that demo-conditioned context. The sample is scored verbatim (`hint_block + token_ids`, slicing the hint's logprobs back off), so the join is BPE-clean and it's robust to tool/multimodal prompts and any number of turns. The scoring reference *is* the live policy — self-distillation names no teacher. opsd builds its own renderer to tokenize the hint block: the tokenizer is always the live policy's (not configurable — there is no separate model), and only the `renderer` family is settable (defaults to `"auto"`, resolved from the policy tokenizer; set it to match a non-auto policy renderer). The demonstration is read from the example's `info[demo_key]`, falling back to a top-level rollout field of the same name (e.g. `answer`).
```toml theme={null}
[orchestrator.algo]
type = "opsd"
demo_key = "demonstration"
```
Scoring runs before curriculum admission, so a rollout that is later rejected still costs its reference compute.
By default, zero-advantage RL tokens are removed after a complete batch cohort has been collected and before its payload is packed for the trainer. This does not backfill the batch. Samples that still carry CE or reference-KL components are retained, while pure zero-advantage RL samples are not shipped. Removing an RL token also removes its trainer/inference mismatch-KL contribution. Set `orchestrator.train.filter_zero_advantages = false` to retain them.
## Curricula
Each training source has a `Curriculum` composed from one `TaskSampler` and any number of named `AdmissionGate`s. The sampler chooses tasks and observes every finalized `list[vf.Episode]`; each gate inspects the same native episodes. The group trains only if every gate admits it. Rejected groups remain observable while the orchestrator samples again to fill the batch.
Samplers and gates can be stateful. Their `state_dict`, `load_state_dict`, and `metrics` methods are included in orchestrator checkpoints and logged under `curriculum//`.
Three small implementations are included:
* `StandardSampler` is the default: it advances the task iterator and cycles finite tasksets in source order.
* `DifficultyPoolSampler` samples finite tasksets with replacement and tracks each task's latest valid mean group reward. Each named pool has an inclusive reward threshold and a relative per-task sampling weight; weight `0` disables sampling from that pool. Unseen tasks use neutral weight `1.0`, so pool observations affect sampling immediately without waiting for a full taskset pass.
* `AdvRangeGate` rejects a group when every trainable-token advantage falls inside `reject_min` through `reject_max`. Unlike the built-in post-batch zero-advantage filtering, rejection requests replacement work. Groups without an advantage stream are admitted.
```toml theme={null}
[orchestrator.train.source.curriculum.sampler]
type = "difficulty_pool"
[orchestrator.train.source.curriculum.sampler.pools.hard]
threshold = 0.25
weight = 0.2
[orchestrator.train.source.curriculum.sampler.pools.normal]
threshold = 0.75
weight = 1.0
[orchestrator.train.source.curriculum.sampler.pools.easy]
threshold = 1.0
weight = 0.2
[orchestrator.train.source.curriculum.gates.low_signal]
type = "advantage_range"
reject_min = -0.05
reject_max = 0.05
```
## Multi-Turn Trajectories
For multi-turn rollouts (tool use, browser environments, long conversations), `prime-rl` records each LLM request/response as an independent **trajectory step** and merges them at training time using best-effort interleaving — with [renderers](#renderers) as the mechanism that keeps the merge safe by construction.
### Extension Property
A sequence of trajectory steps has the **extension property** when each successive step's prompt contains all previous prompts and completions as an exact prefix. The trainer relies on this property — when it holds:
* Multiple steps merge into one training sample.
* Compute scales as $O(T)$ in the trajectory length.
When it breaks (chat template strips past thinking, environment compacts context, an agent hands off to a sub-agent, etc.), the trainer starts a new training sample from that step:
* Graceful fallback to multiple samples — no corrupted data.
* Worst case (every step breaks extension) is $O(T^2)$.
### Best-Effort Interleaving
Concretely:
```
5-step trajectory where extension breaks at step 4:
steps 1–3: extension holds → merged into Sample 1
step 4: extension breaks (e.g. thinking stripped from history)
steps 4–5: extension holds → merged into Sample 2
result: 2 training samples instead of 5
```
The orchestrator enforces an **exact prefix invariant**: the prompt at turn $t$ must be the exact concatenation of prior messages exactly as the LLM originally generated them. If turn 2's prompt is `U1, A1', U2` while `A1' ≠ A1`, the orchestrator can't safely merge — either choice produces logprob drift between trainer and inference. Starting a fresh sample is the only correct behavior, so that's what happens.
### Renderers
Best-effort interleaving works because the renderer guarantees the exact-prefix invariant *by construction* — it never re-renders prior turns, so it can't lose tokens to chat-template normalization, BPE retokenization drift, or thinking stripping. A renderer turns a model's chat template into a Python object that can:
* `render_ids(messages)` — tokenize messages to ids the inference engine accepts.
* `parse_response(completion_ids)` — recover structured `(content, reasoning_content, tool_calls)` from sampled ids.
* `bridge_to_next_turn(prev_prompt_ids, prev_completion_ids, new_messages)` — extend the previous turn's tokens verbatim with the new environment turn, instead of re-rendering history.
When `bridge_to_next_turn` succeeds, the trainer sees the exact token stream the sampler produced; when it can't be proven safe (e.g. the renderer is `DefaultRenderer` and the template's stop sequence is unknown), it returns `None` and the orchestrator falls back to a full re-render — which triggers the new-sample fallback above.
A common source of breakage in the absence of a hand-coded renderer is models like Qwen3 whose chat templates strip past `` blocks across user turns:
```python theme={null}
from transformers import AutoTokenizer
tok = AutoTokenizer.from_pretrained("Qwen/Qwen3-0.6B")
messages = [
{"role": "user", "content": "U1"},
{"role": "assistant", "content": "R1A1"},
{"role": "user", "content": "U2"},
]
tok.apply_chat_template(messages[:1], tokenize=False)
# <|im_start|>user
# U1<|im_end|>
tok.apply_chat_template(messages, tokenize=False)
# <|im_start|>user\nU1<|im_end|>\n<|im_start|>assistant\nA1<|im_end|>\n<|im_start|>user\nU2<|im_end|>
# (the R1 from turn 2 is gone)
```
Hand-coded renderers ship for `qwen3`, `qwen3-vl`, `qwen3.5`, `glm-5`, `glm-4.5`, `minimax-m2`, `deepseek-v3`, `kimi-k2`, `kimi-k2.5`, `nemotron-3`, `gpt-oss`; anything else falls back to `DefaultRenderer` (a generic `apply_chat_template` wrapper). Pick one via:
```toml theme={null}
[orchestrator.renderer]
name = "auto" # detect from tokenizer; pass an explicit name for fine-tunes
```
For the full design rationale (failure modes ruled out, empirical token-identity comparison against `apply_chat_template`, when to write a hand-coded renderer), see [the renderers writeup on the Prime Intellect blog](https://www.primeintellect.ai/blog/renderers) — the canonical reference.
### Discontinuous Trajectories
Some envs are discontinuous by design — e.g. a main agent delegating to a sub-agent and getting back only a summarized result, not the sub-agent's whole conversation. Best-effort interleaving handles this naturally: each agent's contiguous turns merge, the handoff starts a new sample. The trainer never sees fabricated extension where there is none.