

Table of Contents
- The Algorithm Abstraction
- Async / Off-Policy Training
- Loss
- Advantage
- Curricula
- Multi-Turn Trajectories
The Algorithm Abstraction
A training algorithm inprime-rl is configured under [orchestrator.train.algo], where type names the algorithm (grpo, opd, sft, …) and the class defaults are its vetted setting. It has two parts:
- Sampling (
algo.sampling) — how train rollouts are produced: which model generates them.sourceis a model reference:"policy"(the live policy, the default) or an inline frozen hosted model. Group sizing stays on the env config (group_size). - The per-token training signal — credit assignment and loss routing, fused; the algorithm’s own parameters sit directly on
algo. One mapping from a finalized rollout to per-token (loss component, weight) pairs — the credit a token gets and the loss that consumes it are two coordinates of the same output. Group-relative algorithms compute credit on the orchestrator and ship per-token advantage streams; reference-KL algorithms query a reference model at batch-ship time (bounded concurrency) and ship its prefill logprobs for the trainer to evaluate against the live policy. Thetypedetermines which loss component consumes the action tokens (rl/ce/ref_kl) and what happens to env-provided observation tokens in multi-turn rollouts (masked out by default;echotrains on them with weighted CE).
rl_weights / ce_weights / ref_kl_weights component weights plus the advantages stream on each training sample) and the trainer just executes them. Adding an algorithm never touches the dispatcher, batch packing, or trainer hot path.
Model References
prime-rl hosts exactly one model: the trainable policy ([orchestrator.model]). Every other model an algorithm uses is an external OpenAI-compatible endpoint, declared inline on the component that uses it. A model reference is either the string "policy" (the live policy) or a frozen hosted model (name + base_url):
teacher slot. opd declares a teacher field (the frozen model whose reverse KL the policy distills toward); sft’s teacher is its sampling.source (the frozen model it imitates); opsd self-distills against the live policy and names no model at all. No role exists outside the algorithm that declares it: the dispatcher, sink, and trainer branch on liveness alone, never on what an algorithm calls a model.
So for opd set [orchestrator.train.algo.teacher]; for sft set [orchestrator.train.algo.sampling.source]; opsd needs neither. opd’s teacher must be a frozen endpoint — it is typed FrozenModelConfig, so "policy" isn’t representable (the KL would be identically zero); opsd’s teacher is the live policy by definition (self-distillation conditioned on a demonstration), so it exposes no reference to configure.
Liveness is a property of the reference, not of any role: rollouts sampled from "policy" get version-salted prefix caches, carry sampling logprobs for importance ratios, and age off-policy as weights update; rollouts and scores from frozen models get a stable prefix cache and never go stale. Frozen models are externally hosted (base_url is required) — prime-rl never launches or updates them, and each env’s algorithm builds its own client pool to the endpoints it declares.
The Algorithms
Thealgo.type names the algorithm, and each type’s class defaults are its vetted setting — picking a type with no other keys IS the algorithm:
Customizing Components
Every key beyondtype is visibly your own assembly — there is no preset layer to diverge from. The vetted setting is the class defaults; what you set is what runs:
ce loss component — the rl and ref_kl components need the live policy’s own sampling logprobs for importance ratios — opd pointed at "policy" is rejected as degenerate (zero KL), sft without a frozen source is rejected (CE on the policy’s own tokens is not a distillation target). A group-relative algorithm with group_size = 1 produces all-zero advantages; the resulting empty batch is caught at runtime (the orchestrator warns and skips it), not at config time.
Per-Env Algorithms
Both components resolve per environment. Each env inherits[orchestrator.train.algo] like any other group default: an env that sets only some params keeps the group’s algorithm with those params changed, and an env that sets a different type runs its own algorithm. So a single run can mix algorithms across envs — e.g. GRPO on math, ECHO on a terminal env:
The Algorithm Classes
At runtime, each env’sTrainEnv (prime_rl.orchestrator.envs) resolves the sampling.source model into the inference pool used for train episodes, and its resolved config builds one of the named algorithm classes in prime_rl.orchestrator.train.algo (one module per algorithm: algo/grpo.py, algo/opd.py, …) from the algorithm config. Algorithm dispatch is keyed on algo.type — it names the algorithm, and each config class’s defaults are its vetted parameterization:
Algorithms operate on native verifier artifacts and annotate their message graphs directly:
async score_episode(episode)— rollout-local scoring as one episode arrives.async score_group(episodes)— group-relative scoring after the cohort completes.
score_group directly and score_episode through finalize_episode, which skips episodes with no trainable sampled tokens. Advantages, reference logprobs, and named loss weights stay on verifier nodes through admission. Only admitted traces are flattened into TrainingSamples.
The algorithm config states which loss component its action tokens feed (action_loss_type, a class variable on each config class). Every class is constructed with its algorithm config plus the one host-owned resource it can’t rebuild — the live policy clients (self.clients). Everything else an algorithm needs it builds from its own config in setup(): opd connects its frozen teacher; opsd builds the renderer for its demonstration hint (tokenizer is always the live policy’s — self-distillation has no separate model). Writing your own algorithm is subclassing Algorithm and overriding the hooks its signal needs (see Authoring an Algorithm). Shared math (efficiency shaping, prefill alignment) lives as plain functions in prime_rl.orchestrator.train.algo.advantage.
Async / Off-Policy Training
prime-rl is asynchronous by default. The trainer and inference always run one step overlapped: while the trainer is producing from rollouts at step , inference is already generating the rollouts for step using . With matched trainer and inference step times this produces fully-overlapped pipeline parallelism — neither side ever idles.
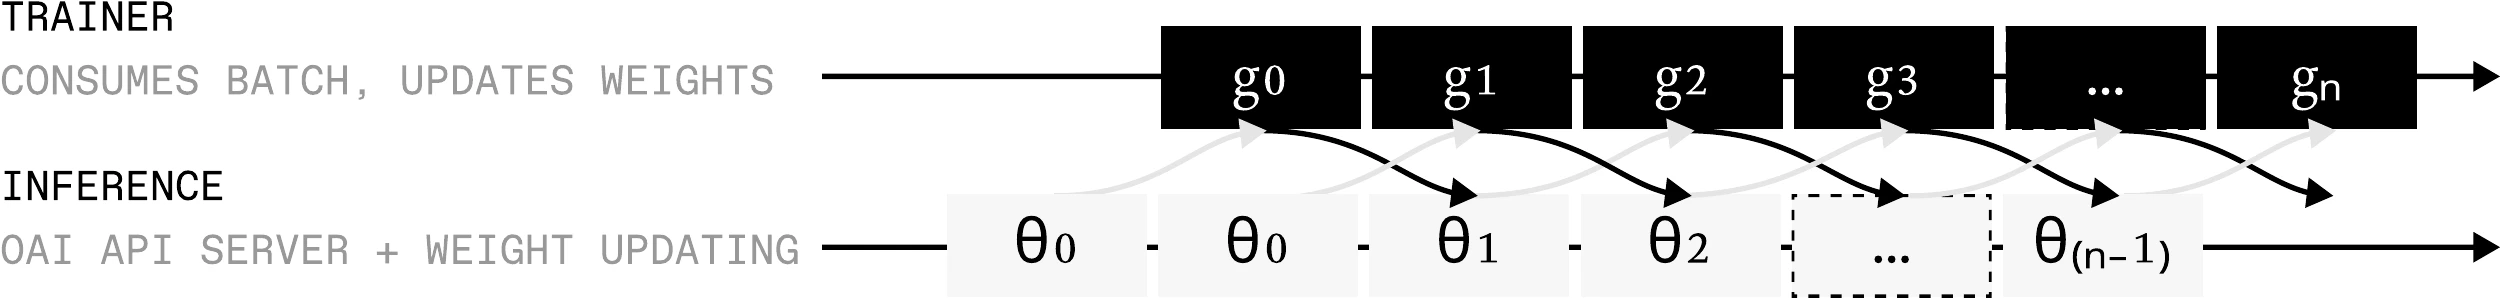
- Trainer produces policy with weights from rollouts .
- Inference produces rollouts from policy .
Loss
Loss Components
The training loss is a sum of three components, each with its own per-token weight stream and its own normalization:rl— the configured RL loss ([trainer.loss]): IPO by default, or optionally IcePop or a custom loss. Fed by the advantage-assigning algorithms (grpo,max_rl,rae,hierarchical_grpo, andecho’s action tokens).ce— masked NLL. Used for frozen-model tokens (sft) and env-observation tokens (echo).ref_kl— the per-token reverse KL to a reference model () as the policy-gradient signal, importance-ratio corrected with a one-sided trust region (opd,opsd). Requiresref_logprobsfrom a reference scoring; the scoring model must be a vLLM server (it’s the only one that exposesprompt_logprobs).
rl_weights / ce_weights / ref_kl_weights on the wire): a weight scales that component’s per-token loss, 0.0 leaves the token out of the component entirely (mask and denominator), and components may overlap on the same token — their gradients sum. Each is the global (all-reduced) count of that component’s member tokens — for rl, the sum of its weights, which is the same count while weights are 0/1 — so the components don’t dilute each other: adding echo observation tokens never changes the rl term’s effective per-token learning rate, and an sft env packed next to a GRPO env doesn’t soften its gradient. Tokens of different components pack freely into the same micro batch, and a plain GRPO run ships no weight streams at all (absent streams mean rl weight 1.0 on every trainable token — the unchanged hot path). Advantages always ship per token (advantages on the wire), assigned as per-token streams from the start — uniform group credit is broadcast over completion tokens at assignment; algorithms with no rl credit (opd, opsd) ship none.
IPO Loss
The default RL loss is INTELLECT Policy Optimization (IPO). It is an importance-weighted policy-gradient term. A symmetric trust region removes tokens whose absolute probability change exceeds : is the policy that generated the rollout. is the current trainer policy. is the token-level advantage. The trust region uses the sampled token probabilities, not their ratio. The knobs under[trainer.loss] are:
Omit
[trainer.loss] to use these defaults. Set type = "ipo" when you specify the section. The ce and ref_kl components are fixed and unaffected by [trainer.loss].
See IPO for why IPO masks by probability instead of ratio, and the GLM-4.5-Air ablation against IcePop behind eps = 0.3.
IcePop Loss
IcePop is an opt-in RL loss that drops tokens whose trainer-to-inference importance ratio falls outside a fixed acceptance band, introduced to stabilize MoE RL in Every Step Evolves: Scaling Reinforcement Learning for Trillion-Scale Mixture-of-Experts Reasoning Models. Accepted tokens retain the importance-weighted policy-gradient term: Enable it explicitly:Custom Loss
[trainer.loss] type = "custom" replaces the rl component. The loss is computed per sequence: you write a function that takes one sequence’s tensors and returns a scalar loss. The trainer iterates and aggregates. inputs.loss_mask selects exactly the rl member tokens (for a plain GRPO run, all trainable tokens).
metrics is averaged across sequences and logged with the other trainer metrics.
Advantage
The per-token training signal is set byalgo.type and the algorithm’s parameters — every signal is a per-token advantage stream, varying in evaluation site (orchestrator vs. trainer). The algo.type values:
Default Advantage
The default advantage is per-group reward minus per-group baseline (DR-GRPO without std normalization). For each prompt’s group ofgroup_size rollouts, every token in rollout receives advantage where is the group mean.
This is intentionally simple — it does the right thing for most envs. Write a named algorithm class when you need group-aware shaping that depends on trajectory metadata (sub-agent rollouts, relative-rank shaping, …) — see Authoring an Algorithm.
A length penalty (length_penalty on the grpo-family algorithms) can be layered on top to discourage rambling. The linear penalty subtracts a single pass_rate-scaled penalty from each reward before the GRPO baseline, combining output tokens (num_output_tokens_weight), input / context tokens (num_input_tokens_weight), and turns (num_turns_weight) — each normalized by the group’s own max for that quantity, with num_input_tokens_weight and num_turns_weight defaulting to 0.1.
length_weighted_baseline = true on the grpo-family algorithms) replaces the plain group mean with , where is the number of trainable (policy-sampled, loss-masked) tokens of rollout , summed across all its turns; it applies after the length penalty. With token-level loss normalization, long rollouts carry more gradient weight, so this baseline makes the per-token advantage zero-mean across the group’s tokens rather than across rollouts.
Prompt-mean loss aggregation (loss_aggregation = "prompt" on grpo and echo; default "token"). By default every rl token in the batch weighs the same, so prompts whose groups produce long trajectories dominate the gradient. With "prompt", the loss is MiMo-V2.6’s prompt-mean (Eq. 1): the mean over prompt groups of , where is the group’s total trainable tokens. MiMo uses it to keep response length from growing too fast. score_group gives each trainable token of the group the rl weight , so each group’s weights sum to 1 and (the summed weights) is the number of groups in the step. Zero-advantage tokens are still dropped from the rl component, so a group with a zero-advantage rollout keeps less than its full weight of 1. All envs with an rl loss in a run must use the same loss_aggregation.
Hierarchical GRPO
GRPO gives each rollout its reward minus the average reward of comparable rollouts. In an ordinary single-agent group, every rollout answers the same task, so one group average is enough. A proposer-solver env is different. Starting from one source task, it produces several proposed problems, then runs several solver attempts on each problem:hierarchical_grpo therefore chooses the average separately for each role:
For example, if three solvers receive rewards
[1, 1, 0] on one proposed problem, their average is 2/3 and their advantages are [1/3, 1/3, -2/3]. Solver rewards from other proposed problems do not affect those values. The proposers are scored separately according to how useful their problems were for the solvers, then compared with the other proposers in the group.
Configure which roles are compared within a single proposed problem with episode_agents. For proposer-solver, that role is solver:
group_size controls how many problems are proposed from each source task. env.n controls how many solvers attempt each proposed problem. If a comparison contains only one trace—for example, a solver when env.n = 1—its advantage is zero.
This algorithm is accepted only for proposer-solver envs. Use the env’s train_proposer and train_solver settings if you want to train only one role.
Self-Play Advantage (RAE)
Group-relative baselines assume the group is exchangeable attempts by one agent. A multi-agent self-play env breaks that: one episode yields one trace per agent, all trainable, and in a zero-sum game the rewards sum to ~0 whatever the policy does — the group mean carries no information, and centering against it converts any structural asymmetry (a first-mover edge) into permanent credit for one agent.rae implements SPIRAL’s role-conditioned advantage estimation (arXiv:2506.24119): each agent keeps an exponential-moving-average baseline of its own rewards, and every trace’s advantage is its reward minus its agent’s baseline — measured against the pre-update baseline (the unbiased order), then folded in at decay (SPIRAL’s α, default 0.95). The algorithm instance is per-env, so baselines are keyed per (env, agent) — the paper’s per (game, role). Advantages are not normalized, and group_size is free (RAE needs no sibling rollouts; group_size = 1 is fine). Baselines live in orchestrator memory and re-warm from 0 over ~1/(1 − decay) traces per agent after a restart.
kuhn-poker’s agents late-bind to the run’s own model — shared-policy self-play against a continuously improving opponent. Pin one agent to a frozen endpoint (env.player1.model = ...) for asymmetric play; its traces are marked untrainable by the env and never reach the advantage computation. A single-agent env under rae degrades to REINFORCE with an EMA baseline.
Authoring an Algorithm
There is no config hook that points at user code — a new credit-assignment scheme is a new named algorithm in the repo. SubclassAlgorithm, assign credit in the scoring hook whose timing fits your signal, and register the class:
MyAlgoConfig to prime_rl.configs.algorithm and its discriminated union, then register "my_algo": MyAlgorithm in ALGORITHM_CLASSES. Pick score_episode for rollout-local work or model calls, and score_group for group-relative credit. assign_advantages takes a scalar or a list aligned to the trace graph’s sampled tokens.
Curriculum admission and metrics can inspect the resulting graph-native streams after group scoring.
Reference Scoring
OPDAlgorithm / OPSDAlgorithm do their model I/O in score_episode: as each episode arrives they query a reference and attach sampled-token reference logprobs to its graph nodes:
opd— score each sample’s own context under theteacher(a frozen model reference) via prefill; fillsref_logprobsfor theref_klloss component (on-policy distillation). Theteacheris typedFrozenModelConfig, so"policy"isn’t representable (the KL would be identically zero).opsd— SDFT: prepend an expert demonstration as a leading system message (template, with a{demonstration}placeholder) and score the sample under that demo-conditioned context. The sample is scored verbatim (hint_block + token_ids, slicing the hint’s logprobs back off), so the join is BPE-clean and it’s robust to tool/multimodal prompts and any number of turns. The scoring reference is the live policy — self-distillation names no teacher. opsd builds its own renderer to tokenize the hint block: the tokenizer is always the live policy’s (not configurable — there is no separate model), and only therendererfamily is settable (defaults to"auto", resolved from the policy tokenizer; set it to match a non-auto policy renderer). The demonstration is read from the example’sinfo[demo_key], falling back to a top-level rollout field of the same name (e.g.answer).
orchestrator.constant_trainer_batch_size defaults to true. The orchestrator filters samples before they count toward the batch target. It collects replacements, so rollout-based batches contain orchestrator.batch_size training traces. Set the option to false to filter after collection without replacement. This setting can improve orchestrator throughput, but it produces smaller trainer batches.
Curricula
Each training source has aCurriculum composed from one TaskSampler and any number of named AdmissionGates. The sampler chooses tasks and observes every finalized list[vf.Episode]; each gate inspects the same native episodes. The group trains only if every gate admits it. Rejected groups remain observable while the orchestrator samples again to fill the batch.
Samplers and gates can be stateful. Their state_dict, load_state_dict, and metrics methods are included in orchestrator checkpoints and logged under curriculum/<env>/.
Three small implementations are included:
StandardSampleris the default: it advances the task iterator and cycles finite tasksets in source order.DifficultyPoolSamplersamples finite tasksets with replacement and tracks each task’s latest valid mean group reward. Each named pool has an inclusive reward threshold and a relative per-task sampling weight; weight0disables sampling from that pool. Unseen tasks use neutral weight1.0, so pool observations affect sampling immediately without waiting for a full taskset pass.AdvRangeGaterejects a group when every trainable-token advantage falls insidereject_minthroughreject_max. Unlike the built-in token filter, it can reject a configurable advantage range. Groups without an advantage stream are admitted.
Multi-Turn Trajectories
For multi-turn rollouts (tool use, browser environments, long conversations),prime-rl records each LLM request/response as an independent trajectory step and merges them at training time using best-effort interleaving — with renderers as the mechanism that keeps the merge safe by construction.
Extension Property
A sequence of trajectory steps has the extension property when each successive step’s prompt contains all previous prompts and completions as an exact prefix. The trainer relies on this property — when it holds:- Multiple steps merge into one training sample.
- Compute scales as in the trajectory length.
- Graceful fallback to multiple samples — no corrupted data.
- Worst case (every step breaks extension) is .
Best-Effort Interleaving
Concretely:U1, A1', U2 while A1' ≠ A1, the orchestrator can’t safely merge — either choice produces logprob drift between trainer and inference. Starting a fresh sample is the only correct behavior, so that’s what happens.
Renderers
Best-effort interleaving works because the renderer guarantees the exact-prefix invariant by construction — it never re-renders prior turns, so it can’t lose tokens to chat-template normalization, BPE retokenization drift, or thinking stripping. A renderer turns a model’s chat template into a Python object that can:render_ids(messages)— tokenize messages to ids the inference engine accepts.parse_response(completion_ids)— recover structured(content, reasoning_content, tool_calls)from sampled ids.bridge_to_next_turn(prev_prompt_ids, prev_completion_ids, new_messages)— extend the previous turn’s tokens verbatim with the new environment turn, instead of re-rendering history.
bridge_to_next_turn succeeds, the trainer sees the exact token stream the sampler produced; when it can’t be proven safe (e.g. the renderer is DefaultRenderer and the template’s stop sequence is unknown), it returns None and the orchestrator falls back to a full re-render — which triggers the new-sample fallback above.
A common source of breakage in the absence of a hand-coded renderer is models like Qwen3 whose chat templates strip past <think> blocks across user turns:
qwen3, qwen3-vl, qwen3.5, glm-5, glm-4.5, minimax-m2, deepseek-v3, kimi-k2, kimi-k2.5, nemotron-3, gpt-oss; anything else falls back to DefaultRenderer (a generic apply_chat_template wrapper). Pick one via:
renderers package loads as a custom renderer: name = "custom" with import_path = "my_module.Class" (or path/to/file.py:Class), see Custom renderers.
For the full design rationale (failure modes ruled out, empirical token-identity comparison against apply_chat_template, when to write a hand-coded renderer), see the renderers writeup on the Prime Intellect blog — the canonical reference.